PERSON DIRECTORY
Jordan Nanos
Jordan Nanos appears in 45 indexed conversations across SemiAnalysis, Big Technology. This directory brings every appearance, source, TL;DR, digest, and transcript into one searchable feed.
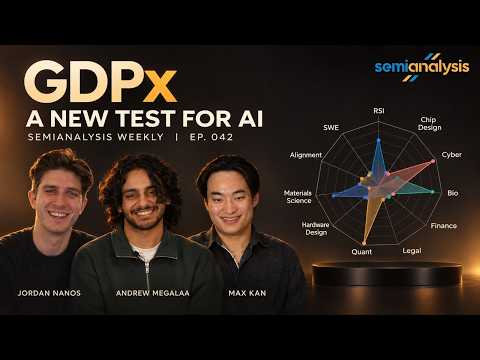
Ep. 042 - GDPx: The Benchmark for Frontier AI | Andrew Megalaa, Jordan Nanos, Max Kan
Jordan NanosMax KanAndrew Megalaa
GDPX targets domains Max Kan expects to capture the first $1 trillion of AI revenue, not routine work.Its 14-provider, mostly private benchmark found some models solved materials-science tasks costing $40–$50 for about $10.Finance and legal remain far from reliable autonomy, while Gemini 4 Carbon trails Astra and Opus, with OpenAI and Anthropic flagships expected soon.
Ep. 040 - ASML Is Building a Hybrid Bonding Tool, and We Have the Patents (AI Supply Chain)
2025 patents point to ASML's unannounced die-to-wafer bonder, several years out, leveraging its metrology and wafer-stage strengths.Logic’s shorter, denser connections offer the clearer efficiency case; HBM’s higher costs and customer requests for fewer layers leave use unlikely before 2029, if at all.Yield still hinges on six-axis alignment, particle control and supplier integration across the conveyor design.
Ep. 039 - [EMERGENCY] Brad Gerstner Cut Our 2027 Forecast in Half. We Raised It. (Datacenters)
Jordan NanosJeremie OntiverosReyk Knuhtsen
SemiAnalysis raised its 2027 data-center forecast from 43 GW to 50 GW, citing building-level tracking against expectations near 25 GW.More than $1 trillion in signed leases and modular builds, with DayOne timelines around nine months versus 18 months traditionally, support delivery; delays and gradual ramps are already modeled.Power remains constrained, while potential data-center oversupply entering 2028 is Jeremie’s main risk, not a formal forecast.
Ep. 038 - Is GLM 5.3 a Mythos-Class Cyber Model From China? (InferenceX)
Kimbo ChenWenyao GaoJordan Nanos
GLM-5.3’s sparse attention eases bandwidth pressure, not KV-cache capacity needs, while cheaper serving could lift HBM and bandwidth demand.AMD’s MI355 reportedly matched B200 cost at 150 tokens per second per user within weeks, underscoring software-driven cost volatility.Post-training reportedly lifted agentic benchmarks by more than 10%, though GLM-5.3 is not Mythos-class and technical disclosure remains limited.
Ep. 037 - Who's Funding the $11 Trillion AI Buildout? (Capital Markets)
SemiAnalysis estimates $11.3 trillion in cumulative AI IT and data-center CapEx for 2024-29, implying roughly $7 trillion of debt by 2029 and $1 trillion of net funding this year.Hyperscaler and NVIDIA backstops, five-year offtakes, and frontier API gross margins near 90% could support financing, but lenders still face residual-value, churn, and execution risks.
Ep. 036 - $200 Buys $12,000 of Opus Tokens, We Bought Every Plan (Tokenomics)
Max KanJordan NanosAndrew Megalaa
Anthropic’s $200 subscription delivered roughly $12,000 of API-equivalent usage in testing, but workload mix—not headline token counts—determines its economics.At roughly 96% cached reads priced at 0.1x or less of fresh input, model ownership may support 40–70% subscription gross margins, while OpenAI’s 50% limit cut and migration to open models remain risks.
Ep. 035 - Tech DD’s, Performance Projections, Supply Chain, Investment Thesis (Consulting)
SemiAnalysis Consulting is turning bespoke AI-infrastructure diligence into scalable products, including a token-supply simulator linking chip deployment, workload allocation, throughput, and token pricing.NeoCloud underwriting centers on contractual survivability: 99.9% availability expectations, sub-90% performance, and mismatched 15–20-year leases versus five-year GPU contracts can threaten financing and trigger remedies, while capacity timelines determine whether clients build or lease.
Ep. 034 - The Fight for Fast Tokens, TPU v7, Vera Rubin, and Engrams (AI Supply Chain, InferenceX)
Jordan NanosCam QuiliciBryan ShanAlec Ibarra
Engrams co-design model architecture and memory hierarchy, retrieving 2-gram and 3-gram embeddings from DRAM or SSD.Hybrid Engram-MoE layers outperform either endpoint, while AgentX traces show 100,000 input tokens at P50 and cache-hit rates above 98%.DRAM offload matters for hundreds of agents at 40–60 tokens/s; TPU V7's early Pareto position still leaves software, utilization, pricing, and demand unresolved.
Ep. 033 - ClusterMAX 3.0 Is Here! Neoclouds Ranked (Neoclouds, GPUs)
Sam HarshePratt BhattJordan Nanos
ClusterMAX 3.0 reshuffles 77 providers: Nebius joins CoreWeave in Platinum, Google Cloud joins Oracle in Gold, while Azure, AWS, Crusoe, and Together fall.Endpoint X finds 75% versus 99% cache hit rates can double an identical bill, while NVIDIA’s backstop universe forecast above $2T by end-2031 leaves SLA discipline, security, and hosted RL’s unproven market as risks.
Ep. 031 - EMERGENCY EPISODE: Are We Doomed? | Jordan Nanos, Doug O'Laughlin, Max Kan, Joey Brookhart
Jordan NanosDoug O'LaughlinMax KanJoey Brookhart
“Pacing” would slow Anthropic’s capability progress without halting training or compute purchases, potentially weakening its strongest internal model.Near-term scarcity and safety workloads keep compute demand elevated, while semiconductor signals increasingly depend on frontier-lab ARR and capacity premiums.Bank hacks, data leaks, or AI-assisted biological attacks could accelerate regulation.